01 / lakehouse2026
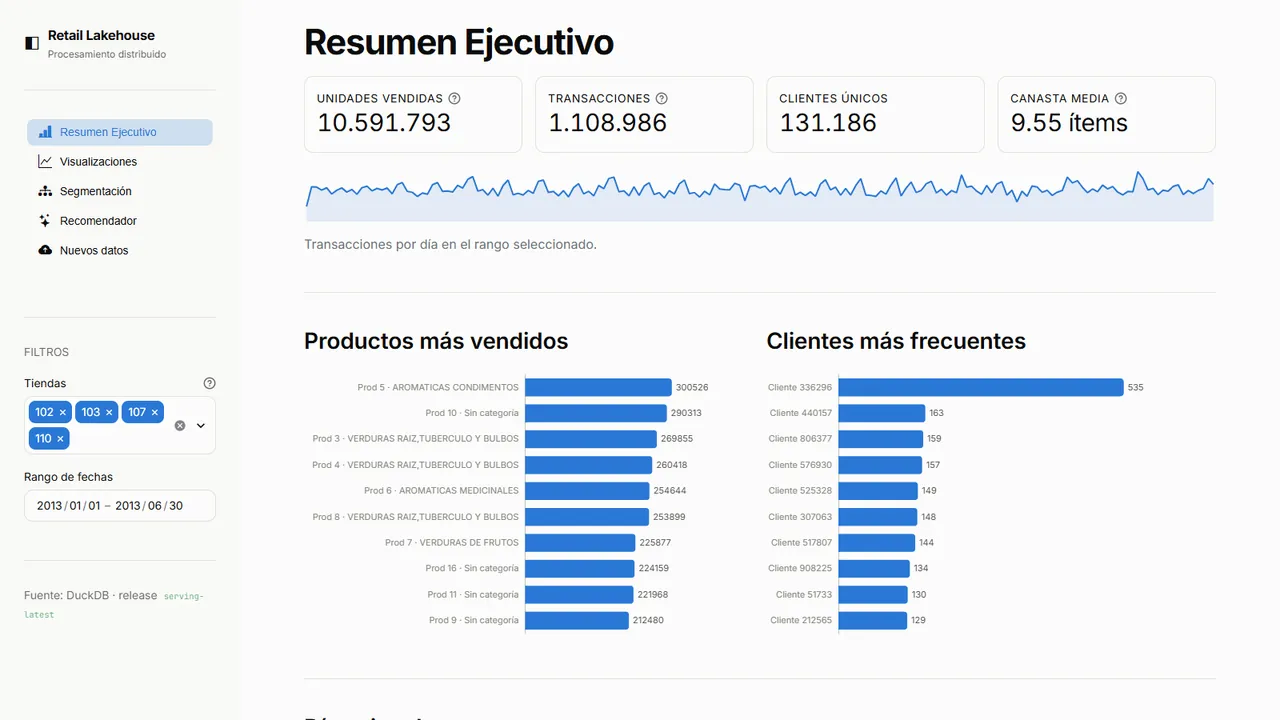
Medallion lakehouse on 1.1M real supermarket baskets
Six months of baskets from four stores — no prices, quantities or transaction IDs — turned into a reproducible PySpark lakehouse, customer segments and product recommendations. Heavy compute runs in CI; the dashboard only reads a 24 MB DuckDB file, so it deploys for free.
- rows from 1.1M baskets
- 10.6M
- customers with a top-10
- 131K
- data contracts
- 26
- Role
- Data & ML engineer
- Impact
- Free deploy: compute split from serving
- PySpark
- Spark MLlib
- DuckDB
- Streamlit
- pandera
- GitHub Actions